LLM systems
Medical Triage HIL: confidence-aware LLM triage
Human-in-the-loop emergency severity prediction
- Timeline
- Jan 2025 to Aug 2025
- Affiliation
- Worcester Polytechnic Institute
- Triage precision
- +20%
- False escalations
- -40%
- Hallucinations
- -50%
- Early critical-case detection
- +60%
What it is
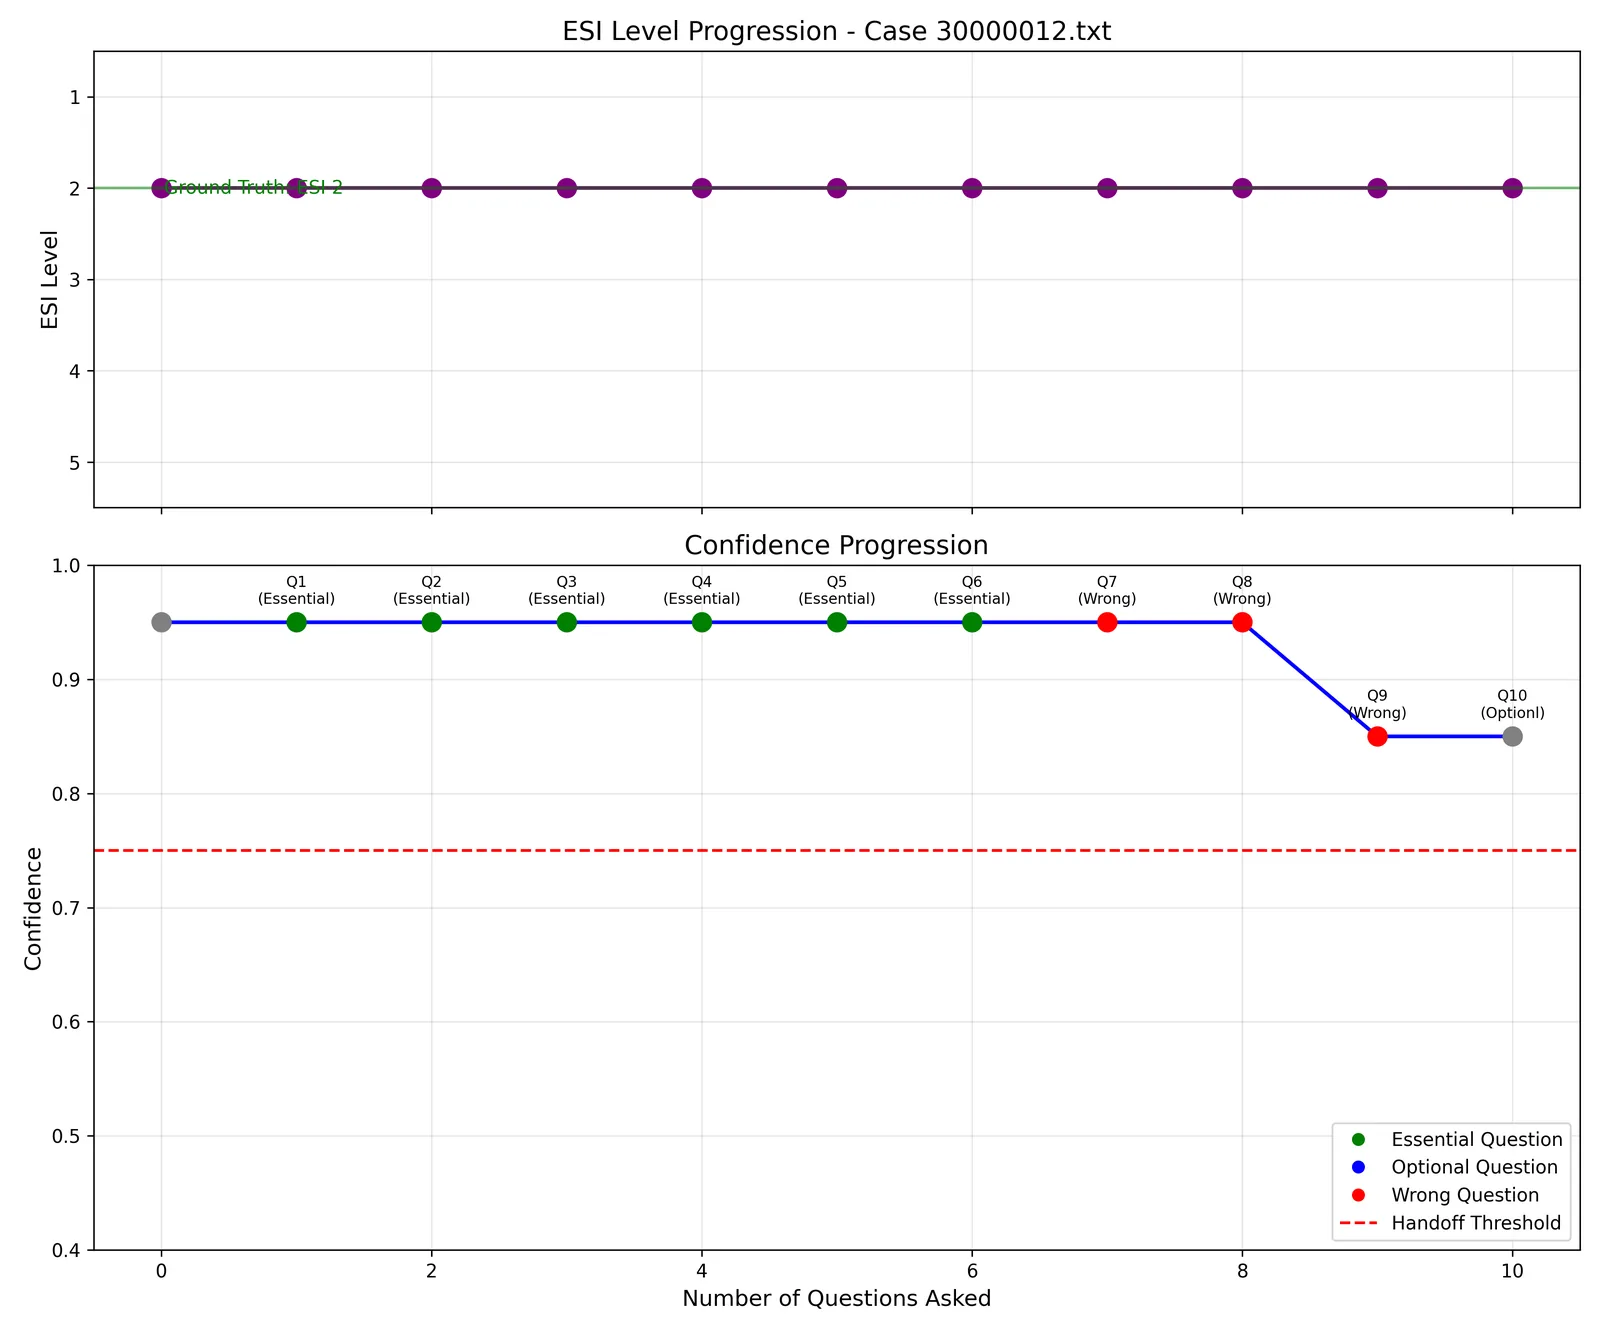
Local LLMs assign Emergency Severity Index levels, reason about handoff risk and track confidence as more patient questions are revealed, with human-in-the-loop review on high-risk escalations.
Problem
LLM triage assistants hallucinate and escalate incorrectly; the question was whether calibrated confidence plus human review could make them safer.
Approach
Ollama-served models (Mistral by default) with risk-factor extraction, incremental QA-based confidence tracking, and elicitation strategies (vanilla, chain of thought, self-probing, top-k, misleading and paraphrased sampling, aggregation); dual-channel decision flow separating escalation from routine guidance; reliability diagrams and calibration plots.
Highlights
Raised triage precision 20% and ESI accuracy 25% while cutting false escalations 40%.
Reduced hallucinations 50% and improved patient-provider alignment 2.3x through the dual-channel flow.
Difficulty-weighted training and GPT-style calibration scoring: errors down 30%, reliability up 35%, early critical-case detection up 60%, non-critical misclassification down 70%.
Research prototype, explicitly not a clinical decision tool.