Research
Where does physics live in vision encoders?
Spatial probing and LoRA ablation of VLM physical reasoning
- Timeline
- Mar 2026 to May 2026
- Affiliation
- Independent research
- Vision-language models
- 3
- Pipeline stages probed
- 4
- LoRA ablation runs
- 15
- Benchmarks
- 3
What it is
Probes where physical properties such as mass, friction, elasticity and stability are encoded across the encoder, projection and LLM stages of Qwen2.5-VL, InternVL 2.5 and LLaVA-OneVision, then fine-tunes five LoRA configurations to find the leverage point for physical intuition.
Problem
Vision-language models trained on internet-scale data show surprising physical reasoning yet fail systematically on intuitive physics, and it was unclear where physical information lives in their pipelines.
Approach
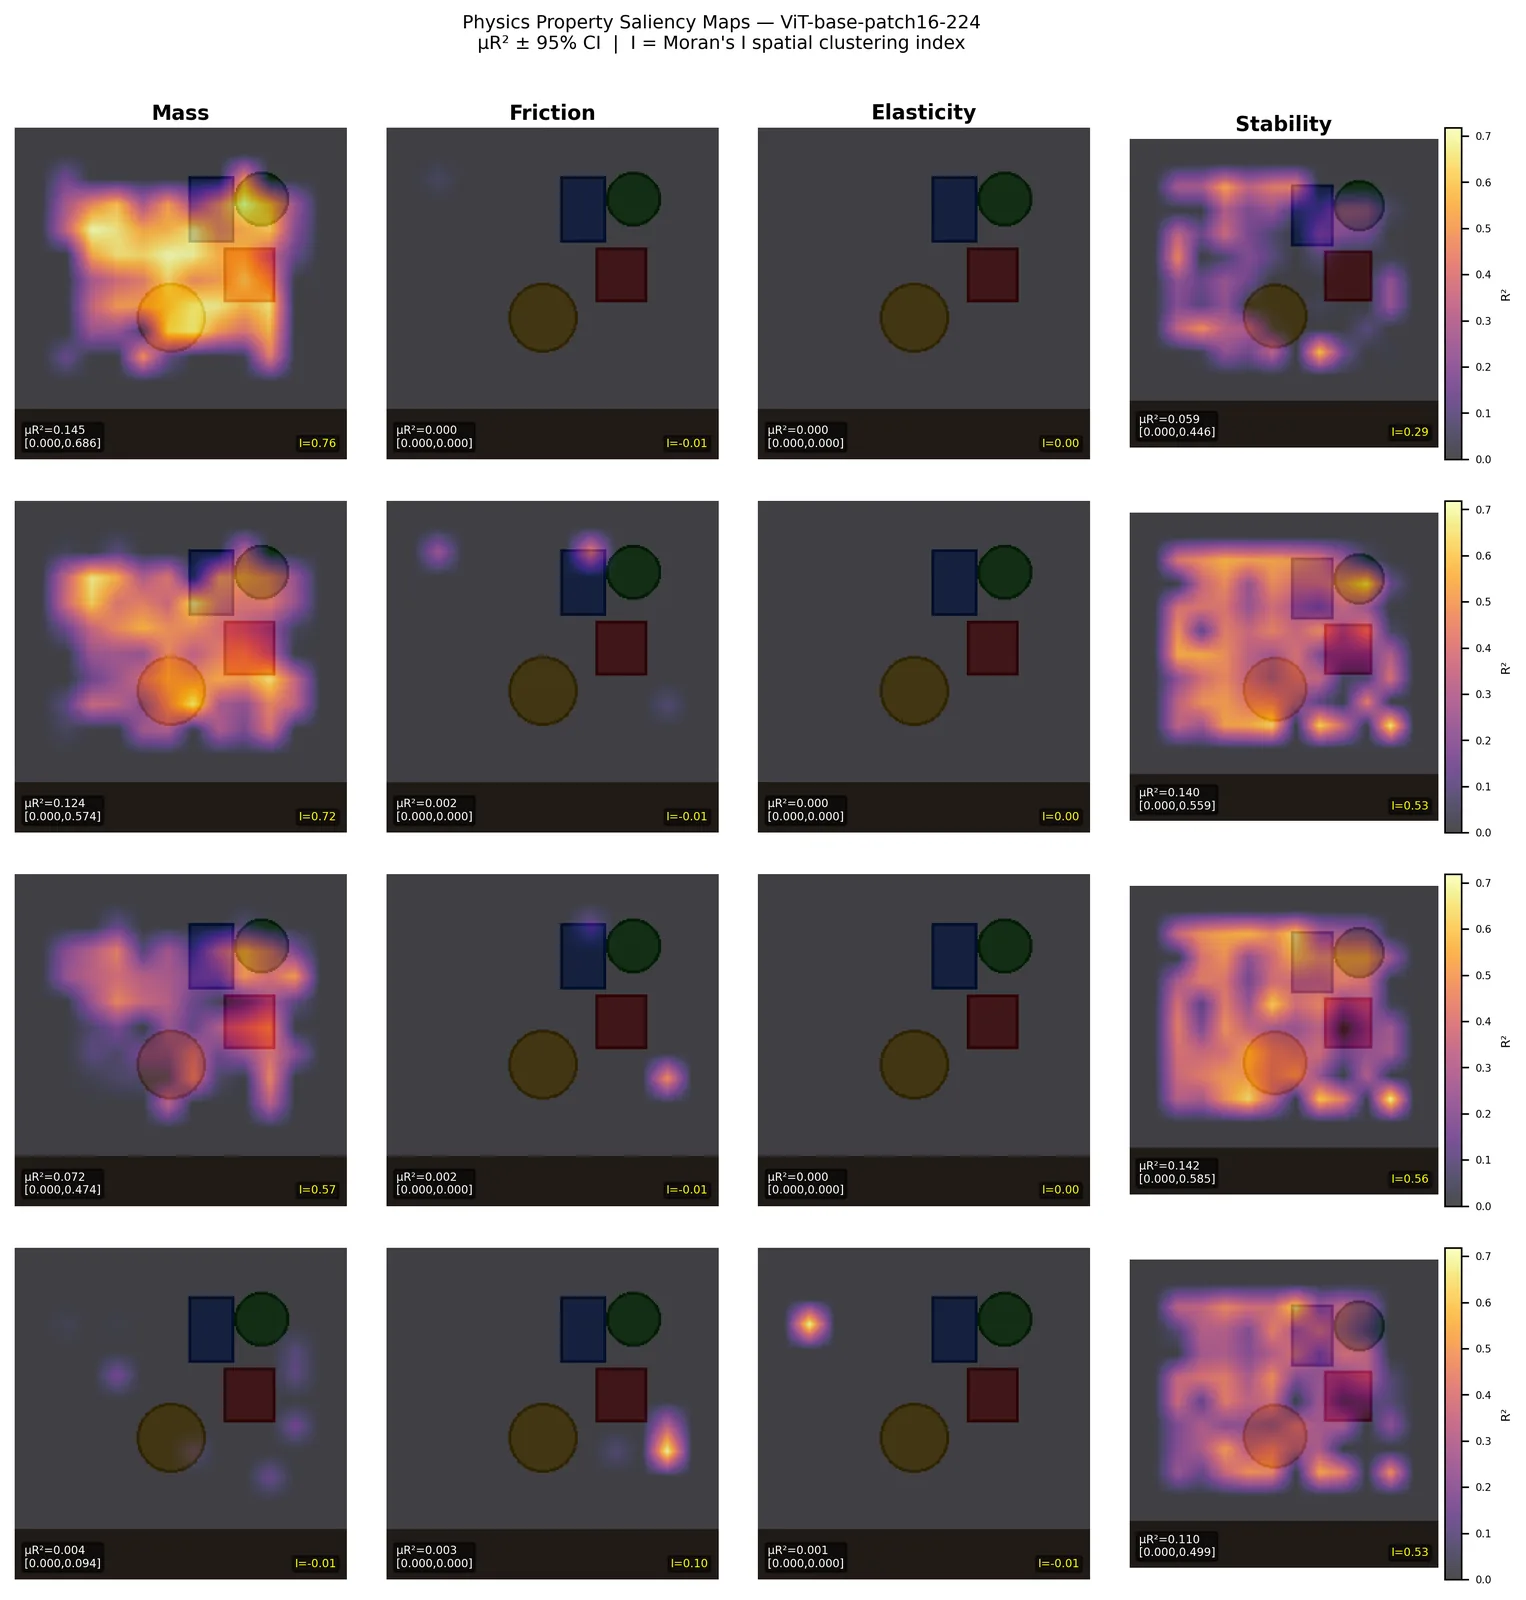
Linear and MLP probes on per-patch activations at four stages using Physion++ ground truth; physics saliency maps as 14x14 heatmaps; R-squared degradation curves across the projection bottleneck; a 3 model x 5 condition factorial LoRA ablation evaluated on PhysBench, GRASP Level 2 and ConservationBench; before-and-after attention analysis.
Highlights
Four research questions covering spatial encoding, pipeline degradation, architectural leverage points and fine-tuning effects.
Hydra-configured codebase with probing, visualization, evaluation and ablation modules.